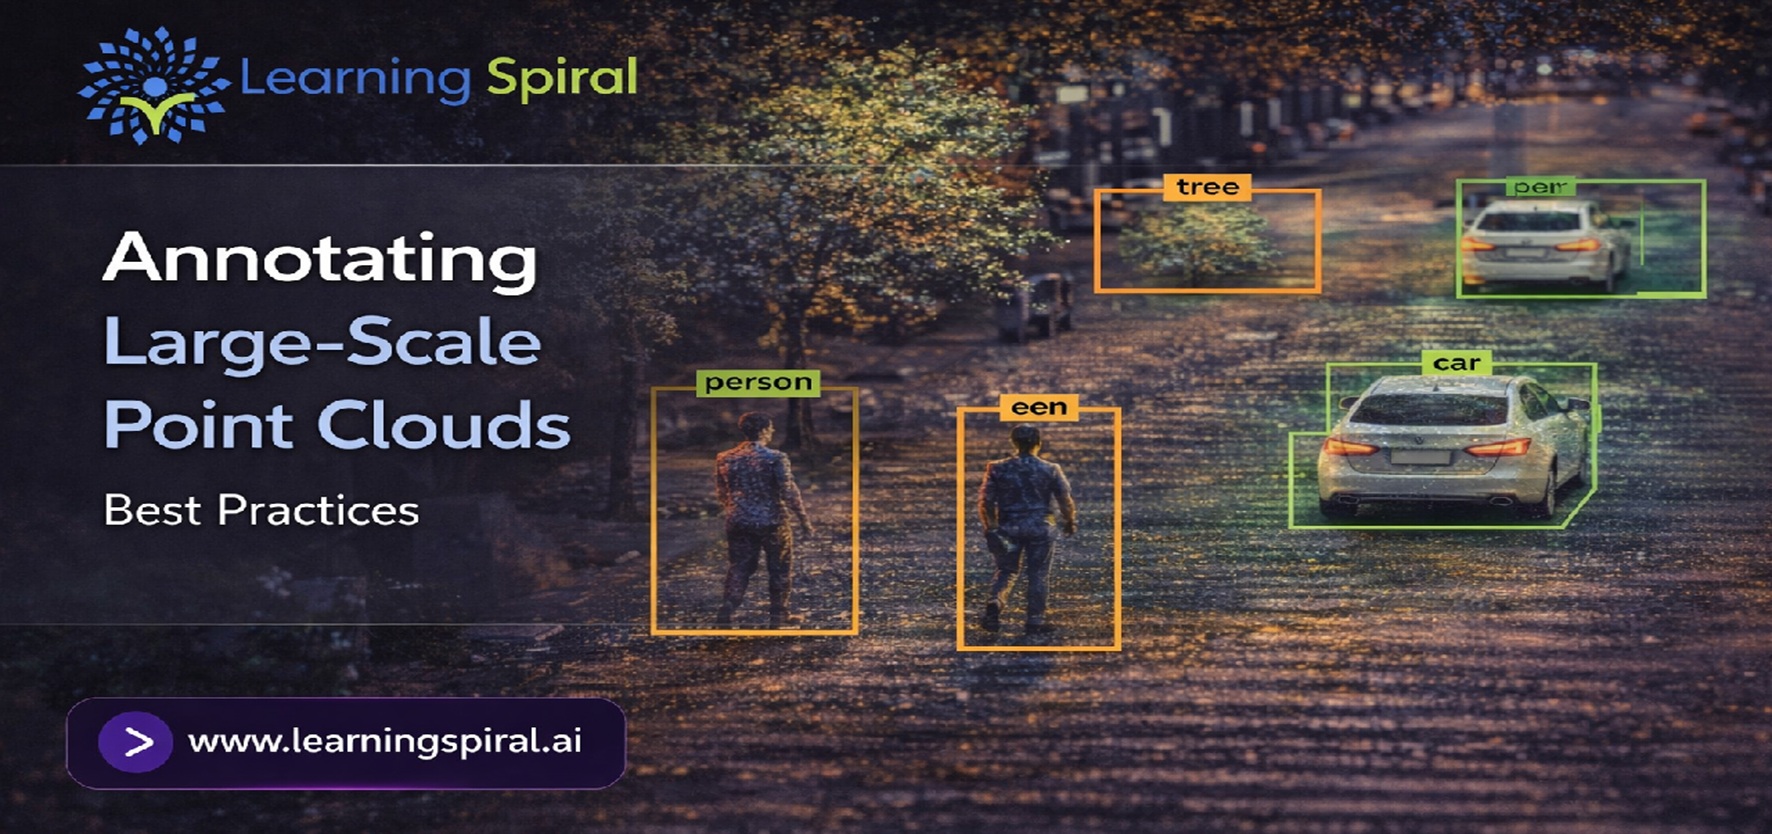
Large-scale LiDAR datasets can contain millions or even billions of spatial points. Learn how structured annotation workflows, clear taxonomies, 3D cuboids, segmentation, quality assurance and human-in-the-loop validation can transform complex point clouds into reliable AI training data.
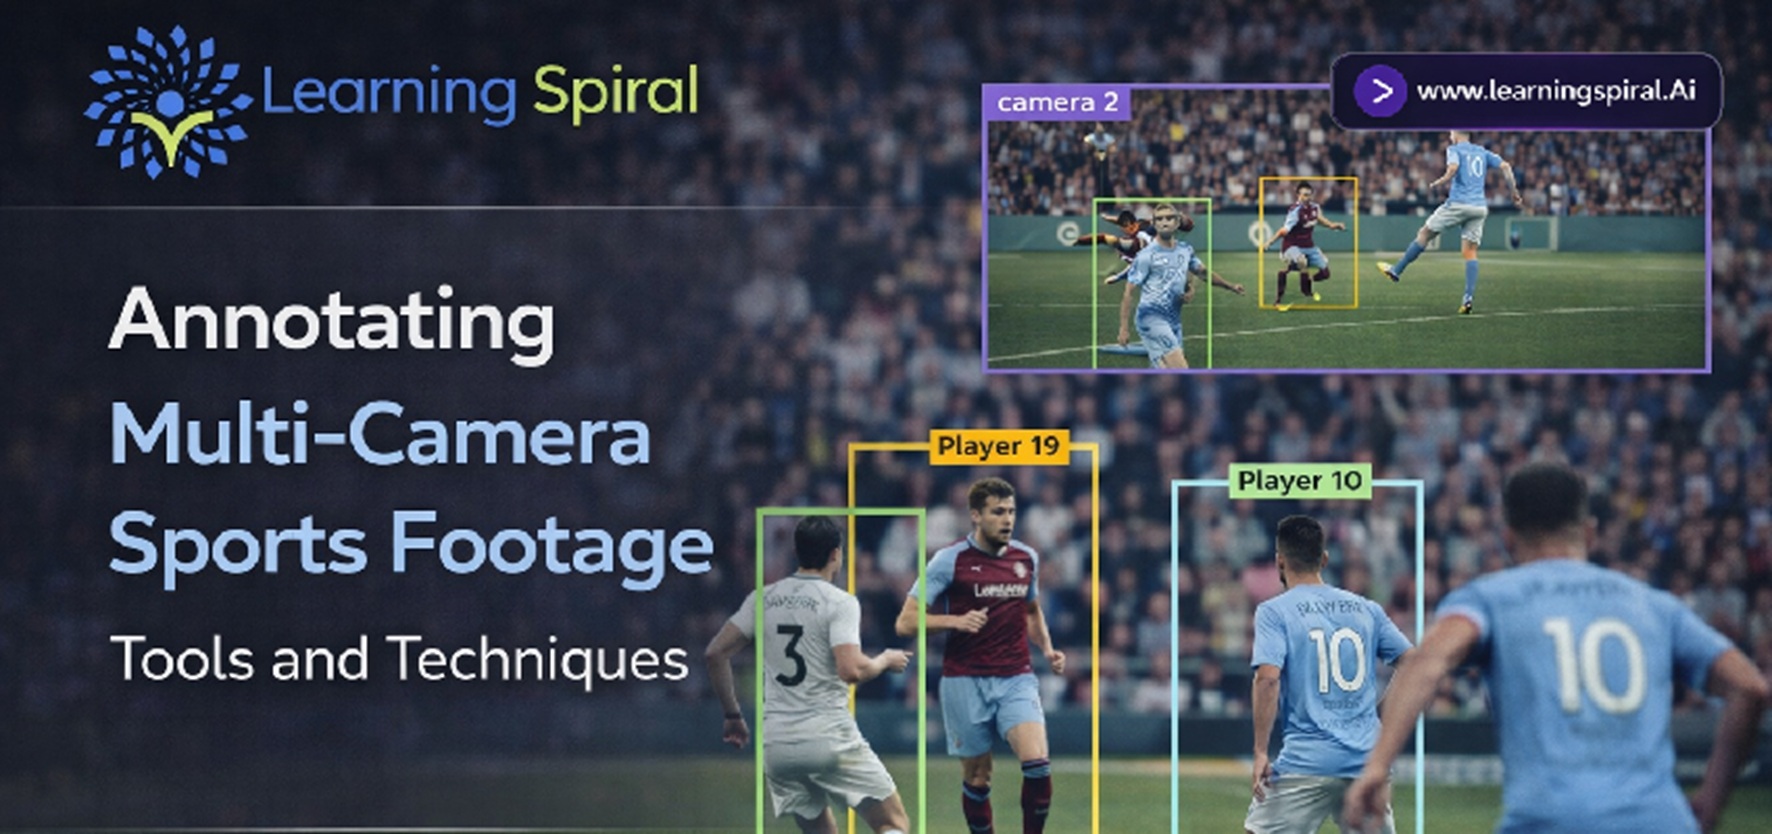
Multi-camera sports footage gives AI a richer view of the game—but also creates complex annotation challenges. Discover how synchronization, player tracking, bounding boxes, keypoints, event tagging and Human in the Loop workflows turn raw sports footage into reliable AI training data.
VR sports training becomes truly intelligent when AI can understand an athlete’s movement, posture, timing and interaction with the environment. Discover how human-labeled datasets transform raw sports footage and sensor data into reliable training intelligence for next-generation VR coaching systems.
Multimodal data annotation connects images, video, audio, text, and other data types to help AI understand not only individual inputs but also the context and relationships between them.
Discover how LiDAR annotation projects convert raw spatial scans into labeled 3D models that support autonomous vehicles, robotics, mapping and physical AI systems.
Image annotation for robotics transforms raw images and videos into structured training data. Discover its types, applications, challenges and role in developing reliable robotic vision systems.
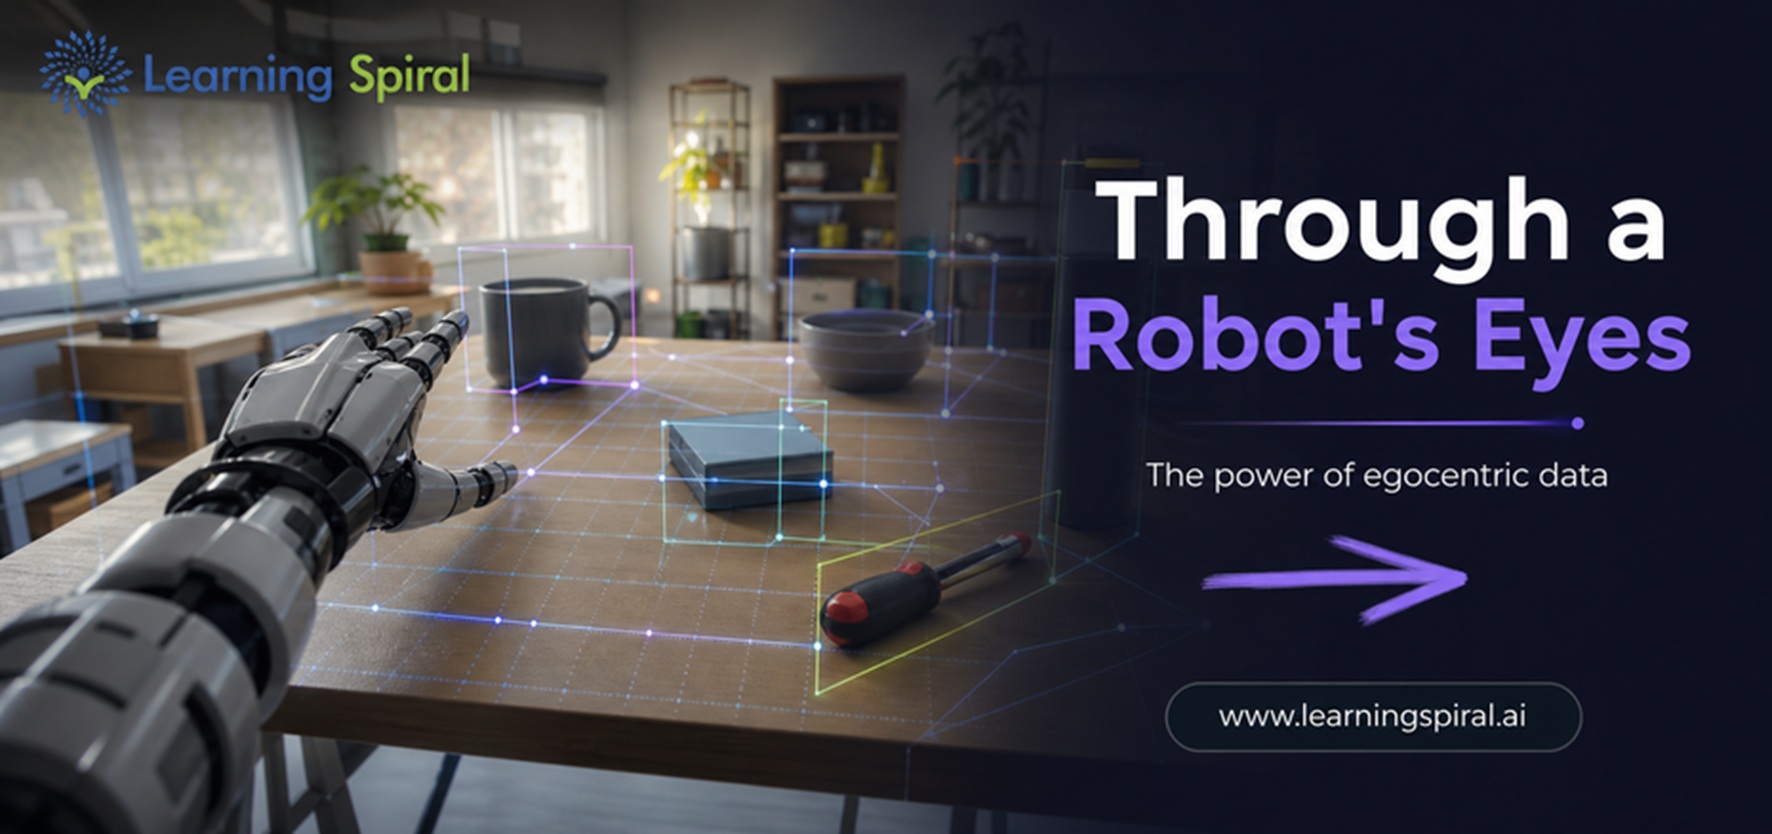
Robots trained on third-person footage often fail in the real world — they've never seen a task from a human's point of view. Egocentric data changes that. Here's why first-person visual data is becoming the backbone of next-generation robotics and embodied AI.
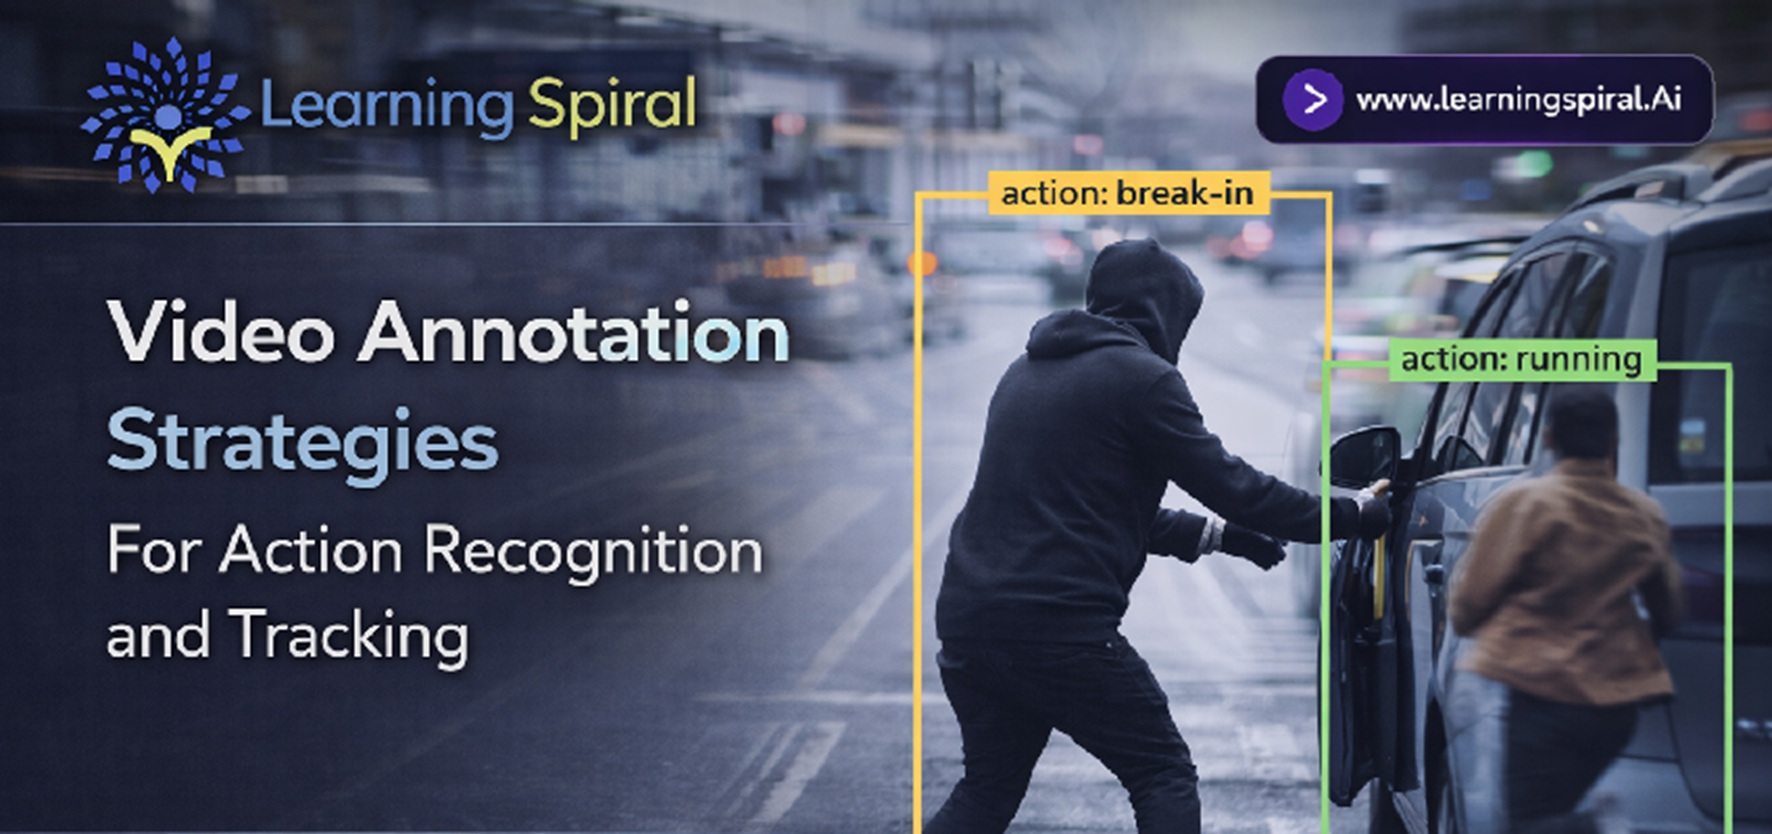
Modern AI models are only as intelligent as the data used to train them. Poorly annotated videos often lead to inaccurate action recognition and unreliable object tracking. This guide explores proven video annotation strategies, quality assurance techniques, and industry best practices for building robust computer vision systems.
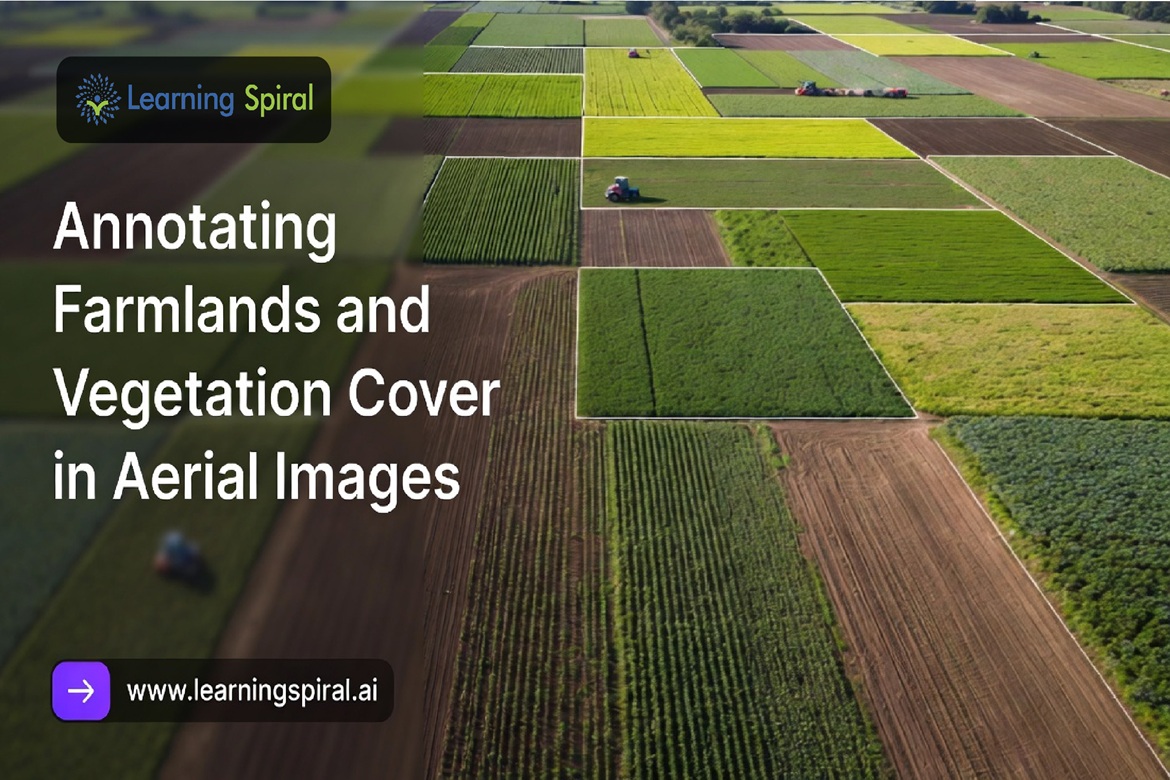
Farmers and agri-tech teams are drowning in aerial data but starving for usable insight. Drones and satellites capture millions of acres of farmland daily, yet raw imagery means nothing to a machine learning model without precise, structured annotation. Here's how that gap gets closed.
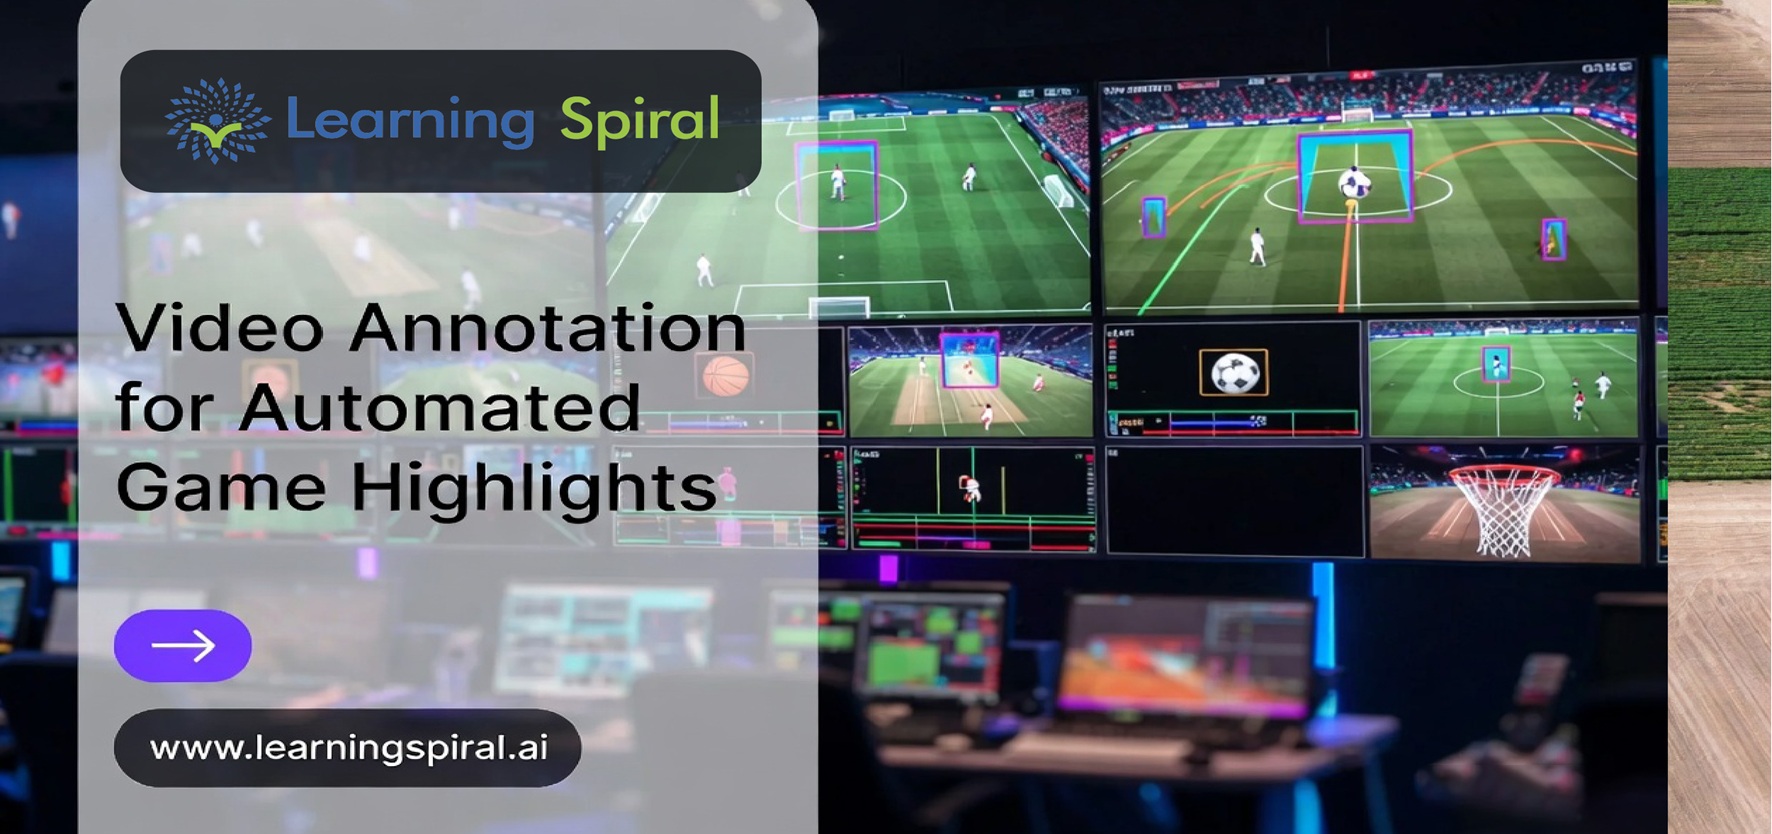
A single football match generates over 5,000 frames of action every minute - and somewhere in there is the goal, the foul, the match-winning save. Automated highlight generation promises to find it instantly. But it only works if the underlying video annotation is right.