A robot moving through a warehouse does not simply need to know that a box exists. It needs to understand where the box is, how far away it is, whether another object is blocking it, how much space exists around it, and whether it can safely move past it.
That is where depth-aware data becomes essential.
Two widely used technologies for capturing this spatial information are LiDAR and RGB-D cameras. Both can produce data that represents the three-dimensional structure of an environment, yet the resulting datasets are far from identical. Their range, point density, appearance information, noise patterns, use cases, and annotation requirements can differ significantly.
For AI teams developing autonomous vehicles, robotics, warehouse automation, augmented reality, smart infrastructure, or other Physical AI applications, understanding LiDAR vs. RGB-D point cloud labeling can help determine what kind of data—and what kind of annotation workflow—the model actually needs.
What Is LiDAR Point Cloud Data?
LiDAR, or Light Detection and Ranging, measures distance by sending laser light toward objects and analyzing the returning signal. A LiDAR sensor can generate large collections of spatial points representing surfaces and objects in the surrounding environment.
Individually, those points do not necessarily tell an AI model whether it is looking at a pedestrian, vehicle, pallet, wall, curb, tree, machine, or road surface.
That understanding must be introduced through accurate labeling.
This is why Lidar Annotation is an important part of many spatial AI workflows. Human annotators or human-supervised annotation systems classify and organize raw LiDAR information into structured training data that machine learning models can learn from.
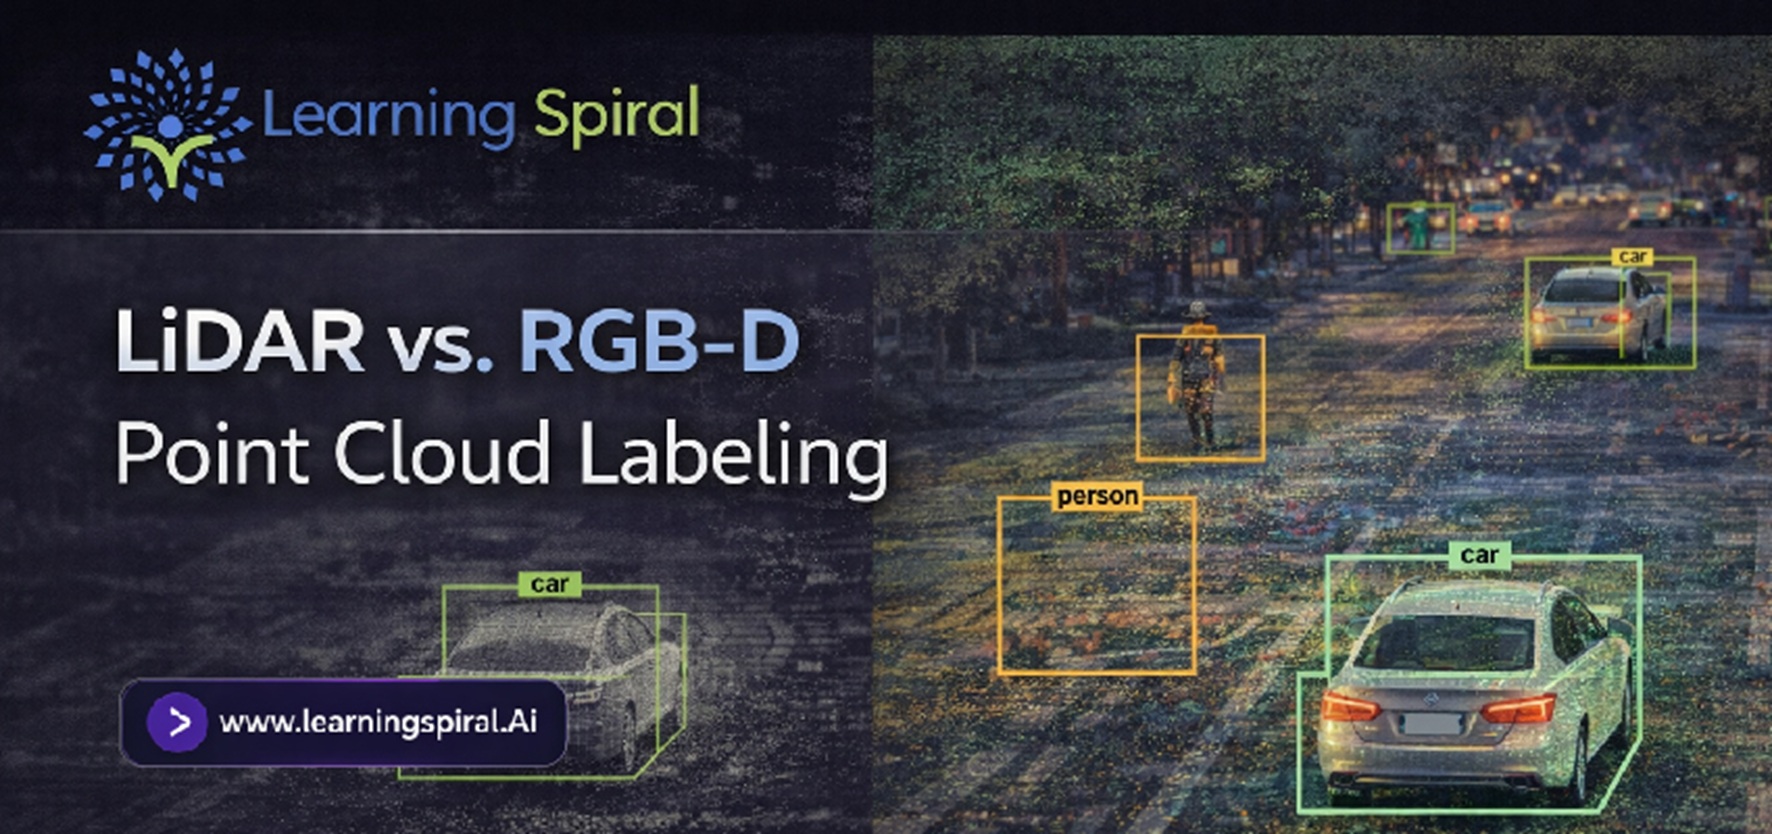
Typical LiDAR annotation can involve 3D cuboids around vehicles and objects, point-level semantic segmentation, instance segmentation, lane or boundary annotation, object tracking across sequential frames, and classification of spatial attributes.
The result is a dataset capable of teaching AI not only what an object is, but where it exists in three-dimensional space.
What Is RGB-D Data?
An RGB-D camera adds depth information to the conventional red, green, and blue visual channels captured by a camera.
In simple terms, an RGB image tells the AI what a scene looks like, while the depth component estimates how far different surfaces are from the camera.
A depth map represents this distance information for surfaces within a scene. With appropriate camera calibration and projection, RGB-D information can also be converted into a three-dimensional point cloud.
This gives AI an interesting combination: visual appearance plus spatial depth.
Imagine a warehouse robot looking at a carton.
The RGB image may capture printed graphics, edges, colors, labels, and texture. The depth information helps the system understand the carton’s distance, approximate shape, position, and relationship with nearby objects.
That combination can be particularly useful for indoor robotics, object manipulation, human-machine interaction, AR/VR applications, inventory systems, and other close-range computer vision applications.
LiDAR vs. RGB-D: The Difference Begins Before Annotation
Although both technologies can represent three-dimensional environments, they do not capture them in exactly the same way.
LiDAR is fundamentally designed around distance measurement. Depending on the sensor and configuration, its point cloud may extend across a much larger environment while preserving useful spatial geometry.
RGB-D systems typically combine visual imagery with per-pixel or near-per-pixel depth information. Their strength is that geometry can be paired directly with rich visual information such as color, texture, patterns, and appearance.
This distinction changes the annotation task.
A LiDAR annotator may primarily work with spatial point distributions, cuboids, trajectories, surfaces, classes, and geometric boundaries.
An RGB-D annotation workflow may require the annotator to reason across both image appearance and corresponding depth information, ensuring that labels remain spatially consistent between the visual and depth representations.
Choosing between the two therefore is not simply a question of which sensor produces “better” 3D data.
It is about what the AI system needs to perceive.
How LiDAR Point Cloud Labeling Works
In a LiDAR workflow, raw spatial scans are converted into structured labels that describe the environment.
For autonomous driving, a scene may contain cars, pedestrians, cyclists, traffic infrastructure, road boundaries, vegetation, buildings, and many other classes. For industrial robotics, the same process may instead focus on machines, racks, pallets, containers, workers, floors, walls, and restricted zones.
Accurate 3D point cloud annotation can help machine learning models learn object dimensions, position, orientation, spatial boundaries, and relationships that would be difficult to infer reliably from flat imagery alone.
Common annotation methods include:
• 3D Cuboid Annotation: Objects are enclosed within three-dimensional boxes representing their width, height, depth, position, and orientation.
• Semantic Segmentation: Individual points are assigned classes such as road, vegetation, building, floor, vehicle, or pedestrian.
• Instance Segmentation: Separate objects belonging to the same class receive independent identities.
• Object Tracking: The same object’s identity is maintained across sequential sensor frames, allowing models to learn movement and trajectories.
• Polylines and Spatial Boundaries: Lane markings, curbs, pathways, edges, or similar structures can be annotated when required by the use case.
These tasks make LiDAR-based Data Annotation considerably more spatial than conventional 2D image labeling.
How RGB-D Point Cloud Labeling Works
RGB-D annotation introduces another layer of information: the relationship between visible image content and measured depth.
An annotator may see a clearly recognizable object in the RGB image while simultaneously using the depth channel to determine how its geometry is separated from the background.
Depending on the AI application, RGB-D labeling can include object detection, semantic segmentation, instance segmentation, surface classification, 3D cuboids, pose information, keypoints, depth-aware object masks, and object relationships.
This can be especially valuable in robotics.
For example, consider a robotic picking system trying to identify products placed closely together inside a container. Color imagery helps distinguish object appearance, while depth provides additional information about separation, distance, orientation, and geometry.
That is why projects involving Image Annotation for Robotics increasingly benefit from multimodal datasets rather than relying on a single visual source.
Point Density Does Not Automatically Mean Better Training Data
One of the most important lessons in 3D Data Labeling is that more points do not automatically create a better Dataset for Machine Learning.
The model needs relevant, consistent, accurately labeled data.
A dense RGB-D point cloud may contain detailed information about nearby surfaces, yet sensor limitations, reflections, missing depth values, occlusion, or calibration errors can still introduce uncertainty.
Similarly, LiDAR data may contain sparse regions or irregular point distributions depending on object distance, material, sensor characteristics, environment, and viewing angle.
The annotation workflow must therefore account for the properties of the sensor rather than treating every point cloud as if it were generated identically.
A high-quality Data Annotation Company should define labeling rules around the actual sensor setup, target environment, ontology, edge cases, and intended model behaviour before large-scale production begins.
The Biggest Annotation Challenge: Occlusion
Real environments are rarely clean.
A pedestrian may stand behind a parked vehicle. A warehouse worker may disappear partially behind a pallet. A robotic arm may block part of an object. Shelves may overlap products. Vehicles may intersect visually at busy junctions.
In LiDAR data, partially visible objects may contain only a limited number of usable points.
In RGB-D data, the RGB view may make an object visually understandable even when its depth boundary is imperfect—or the opposite may happen.
The annotation guidelines therefore need explicit rules for partially visible objects.
Should the annotator label only the observed geometry?
Should a 3D box estimate the complete object?
At what visibility threshold should an object be ignored?
Should heavily occluded objects receive a separate attribute?
Without consistent answers, two annotators can interpret the same scene differently. That inconsistency eventually becomes noise in the AI training data.
Calibration Matters in RGB-D and Multisensor Annotation
When RGB imagery, depth information, LiDAR, or additional cameras are used together, synchronization and calibration become extremely important.
The same object must correspond correctly across different representations.
If a person appears in one position in an RGB frame but their depth points are spatially displaced because of calibration problems, even carefully drawn labels may become unreliable.
For multisensor annotation projects, quality assurance should therefore evaluate more than the visual neatness of labels.
Teams should validate coordinate alignment, class consistency, object IDs, occlusion handling, geometry, timestamps where applicable, and consistency across sequential frames.
This is particularly important for sensor-fusion datasets used in autonomous systems.
LiDAR for Autonomous Vehicles and Outdoor Spatial AI
LiDAR is widely relevant to applications where accurate 3D environmental understanding is important.
For autonomous mobility, models need to recognize vehicles, pedestrians, cyclists, road infrastructure, obstacles, and navigable areas while also understanding their spatial relationships.
Combining LiDAR labeling with image annotation for autonomous vehicles can support richer perception datasets by bringing together geometric and visual context.
A camera might help identify whether an object is a traffic sign.
LiDAR can add information about where that sign exists in three-dimensional space.
When the training pipeline is carefully designed, multiple sensors can complement rather than duplicate one another.
RGB-D for Robotics and Indoor Intelligence
RGB-D cameras can be particularly useful when AI systems operate near people and objects inside structured spaces.
Consider a warehouse robot approaching a shelf. It may need to identify a carton from visual information, estimate its distance, understand whether another package blocks access, calculate the object’s orientation, and determine where a robotic gripper should move.
Similar requirements appear in service robotics, manufacturing, smart retail, AR navigation, healthcare environments, research laboratories, and human-robot interaction.
For these projects, depth-aware Image Annotation can provide a richer training signal than RGB imagery alone.
This is where AI Training Data Services must be designed around the physical task that the machine eventually needs to perform—not simply around the type of file supplied by the client.
What About Using LiDAR and RGB-D Together?
Sometimes the most useful answer is not LiDAR or RGB-D.
It is multimodal sensing.
Modern computer vision and Physical AI systems can combine multiple sources, such as cameras, depth cameras, LiDAR, radar, video, or other sensor data.
Each modality contributes different information.
RGB captures appearance.
Depth represents distance.
LiDAR captures detailed spatial geometry across its sensing environment.
Other sensors may contribute motion, velocity, thermal information, or additional environmental signals.
The challenge then becomes annotation consistency.
A car labeled as one object in a camera frame must correspond logically to the same physical object represented in the associated point cloud or sensor sequence.
This is where Human in the Loop (HITL) workflows remain important. Automation can accelerate repetitive annotation processes, but trained human reviewers can resolve ambiguous scenes, unusual objects, poor sensor returns, complex occlusion, and difficult edge cases.
Which One Should Your AI Project Choose?
There is no universal winner in LiDAR vs. RGB-D point cloud labeling.
The right choice depends on the environment, sensing distance, model objective, deployment conditions, required spatial accuracy, available hardware, and the type of information the AI must understand.
• Consider LiDAR when your application depends heavily on spatial geometry, environmental mapping, autonomous navigation, road-scene understanding, large physical spaces, or 3D object detection.
• Consider RGB-D when your application needs both visual appearance and depth information at closer operating ranges, particularly for indoor robotics, object manipulation, AR/VR, or human-machine interaction.
• Consider multimodal annotation when neither modality provides enough context by itself and the model must combine visual and spatial intelligence.
The sensor selection is only the first decision.
The quality of the labels ultimately determines how effectively that information becomes usable AI training data.
Why Annotation Quality Matters More Than Sensor Choice Alone
Even sophisticated sensing hardware cannot compensate for inconsistent ground truth.
If objects are labeled differently across frames, cuboids do not match actual geometry, classes overlap, point segmentation is inconsistent, or IDs change during tracking, the model can learn those errors.
A reliable Data Labeling Company therefore needs a structured annotation pipeline covering clear ontology creation, annotator training, edge-case documentation, quality checks, feedback loops, and final dataset validation.
For large Data annotation projects, quality control should begin during production rather than only after the dataset has been completed.
This helps detect systematic labeling problems early and reduces costly rework.
How Learning Spiral AI Supports 3D and Multimodal AI Data
Learning Spiral AI provides scalable Data labeling & annotation services for computer vision, robotics, autonomous systems, and other AI applications.
Our capabilities cover Lidar Annotation, 3D Point Cloud Annotation, Data Annotation, Data Labeling, Image Annotation, Video Annotation, Bounding Box Annotation, Image Labeling, Human in the Loop (HITL), Image Annotation for Robotics, Physical AI Data Collection, Egocentric Data Collection, and AI Training Data Services.
For LiDAR and point-cloud workflows, our focus is on turning raw spatial information into structured, model-ready datasets through project-specific annotation processes and quality-control workflows.
For multimodal projects, annotation requirements can be designed around the relationships between camera, depth, point-cloud, video, and other sensor information so that models receive coherent training data rather than disconnected labels.
Whether you are building autonomous perception, robotic navigation, warehouse intelligence, spatial AI, computer vision, or another real-world machine learning application, the objective remains the same:
Turn complex real-world data into training data an AI model can reliably understand.
Final Thoughts
LiDAR and RGB-D allow machines to move beyond simply seeing objects toward understanding the three-dimensional environments around them.
But the raw sensor data is only the beginning.
Accurate labeling gives those points meaning.
LiDAR annotation can teach models about objects, geometry, movement, boundaries, and large-scale spatial environments. RGB-D annotation can combine appearance with depth to support detailed perception and interaction in closer-range environments.
And when multiple sensors work together, carefully designed annotation can help transform separate streams of information into a coherent Dataset for Machine Learning.
The question, therefore, is not simply:
“Should we use LiDAR or RGB-D?”
A better question is:
“What spatial information does our AI need to understand—and how accurately must we label it?”
That is where effective 3D data annotation begins.
Build Better Spatial AI with High-Quality Training Data
Working with LiDAR, RGB-D, robotics, autonomous vehicles, or complex 3D datasets?
Learning Spiral AI can support your project with scalable Data Annotation Services, Lidar Annotation, 3D Point Cloud Annotation, Image Annotation, Video Annotation, Bounding Box Annotation, and AI Training Data Services designed around your model and dataset requirements.
